Zhipu AI Launches and Open-Sources GLM-4.6V Series: Native Multimodal Tool Calling Turns Vision into Action — The True Agentic VLM Revolution
On December 8, 2025, Zhipu AI officially released and fully open-sourced the GLM-4.6V series multimodal models, including the high-performance GLM-4.6V (106B total params, 12B active) and the lightweight GLM-4.6V-Flash (9B). Featuring groundbreaking native multimodal function calling — where images serve directly as parameters and results as context — plus a 128K token window for handling 150-page docs or hour-long videos, it achieves SOTA on 30+ benchmarks at comparable scales. API prices slashed 50%, Flash version free for commercial use, weights and code now on GitHub/Hugging Face — igniting a frenzy for visual agents in coding, shopping, and content creation.
Tencent Unleashes Hunyuan 2.0: 406B MoE Powerhouse with Industry-Leading Reasoning Efficiency and 256K Context Mastery
Tencent officially launched Hunyuan 2.0 (Tencent HY 2.0) on December 5, 2025 — featuring dual variants: HY 2.0 Think for deep reasoning and HY 2.0 Instruct for rapid responses. Built on a massive 406B-parameter MoE architecture (32B active), it supports 256K context windows while delivering top-tier inference speed and efficiency. Already live in Yuanbao and ima apps, with Tencent Cloud APIs open, early benchmarks show massive gains in math, science, coding, and long-context tasks — positioning it as a domestic frontrunner against global giants.

Google Opens Public Beta for Gemini 3 Deep Think: The "Olympiad Gold Medal-Level" Reasoning Mode That Turns AI into a True Thinking Partner
On December 4, 2025, Google officially rolled out Gemini 3 Deep Think mode in public beta to Google AI Ultra subscribers — building on the Gemini 3 Pro launch last month, this enhanced reasoning engine leverages parallel hypothesis exploration to achieve unprecedented performance on PhD-level science, math olympiad-caliber logic, and long-horizon planning. Inheriting the gold-medal prowess from its Gemini 2.5 predecessors at IMO and ICPC, Deep Think scores 41% on Humanity’s Last Exam (without tools) and 45.1% on ARC-AGI-2, marking the first time an AI publicly demonstrates "deep deliberation" at scale. Early testers report 4x deeper insights on complex queries, cementing Gemini's frontier lead.
Pollo AI Secures $14 Million Seed Funding: The "AI CapCut" Aggregator Explodes with 6M MAU and Profitability in Record Time
Singapore-based Pollo AI announced a $14 million seed round on December 8, 2025 — led by Gaorong Capital (Gao Cheng) with ZhenFund (True Fund) following — marking its first institutional funding. The all-in-one AI video and image generation platform integrates top models like Kling AI, Runway, Veo, and Stable Diffusion, boasting 20M+ registered users, 6M+ MAU, and $20M+ annualized revenue while already profitable since May. Funds will fuel model aggregation, product upgrades, and global expansion, positioning Pollo as the "video version of Canva" in a crowded creator economy.

LiblibAI Launches Seedream 4.5: ByteDance's Latest AI Image Beast Goes Live — Crushing Consistency and Multi-Reference Limits
LiblibAI, China's powerhouse AI creation platform, rolled out full access to ByteDance's Seedream 4.5 on December 5, 2025 — a massive upgrade boasting unbreakable subject consistency, up to 14 reference image fusion, razor-sharp small text rendering, and cinematic 4K fidelity. Creators can now lock characters across poses/scenes, blend multi-source refs without morphing artifacts, and nail complex posters with flawless typography — all in seconds. Early users report 5x faster professional workflows, positioning Seedream 4.5 as the new king for ads, e-commerce, and storyboarding, outpacing rivals in native editing cohesion.
Xiaohongshu Fully Acquires "Diandian": Integrating AI Life Search Engine to Accelerate Content-to-Commerce Closed Loop
On December 4, 2025, enterprise registry data revealed that Xiaohongshu's core operating entity, Xingyin Information Technology (Shanghai) Co., Ltd., completed a 100% acquisition of Shanghai Shengdong Shizhang Technology Co., Ltd. — the developer behind the strategic AI search product "Diandian". Original shareholder and legal representative Wei Kuang (a longtime Xiaohongshu senior product manager) fully exited. This move formally integrates Diandian — Xiaohongshu's incubated AI life search assistant — into the group, bolstering its AI-driven push in lifestyle scenarios and signaling an aggressive play to capture the "content + search + transaction" entrance amid fierce competition from WeChat and Douyin.
Doubao Unveils Seedream 4.5: The Commercial-Grade Image Creation Model Built for Production Power — Crushing Midjourney in Speed and Realism
ByteDance's Doubao AI platform launched Seedream 4.5 on December 12, 2025 — a hyper-optimized image generation model laser-focused on commercial workflows like advertising, e-commerce visuals, and brand asset pipelines. With enterprise-grade consistency, ultra-fast 3-second generations, built-in style libraries for 50+ industries, and seamless integration with Doubao's Canvas and Jinshu document tools, it delivers production-ready assets at scale. Early enterprise adopters report 8x faster visual iteration and 60% cost reduction vs. Midjourney or Firefly, instantly making Seedream the default choice for China's booming creator economy.
Anthropic Acquires Bun: The JavaScript Powerhouse Fueling Claude Code's $1B Explosion and the Rise of AI-Native Dev Stacks
Anthropic announced its first-ever acquisition on December 2, 2025: Bun, the lightning-fast JavaScript runtime, bundler, and toolkit that's already the backbone of Claude Code. With Bun's 7M+ monthly downloads and 82K GitHub stars, this move supercharges Anthropic's AI coding empire — Claude Code hit $1B ARR just six months post-launch — by embedding high-performance execution directly into agentic workflows. Bun stays open-source and MIT-licensed, but expect turbocharged integrations for Claude Agent SDK and beyond, signaling AI's vertical march into the full SDLC.

LiblibAI Launches Kling O1: The All-in-One Video Model Turning Prompts into Pixar-Grade Worlds — Kicking Off the Multimodal Video Revolution
LiblibAI rolled out Kling O1 on November 30, 2025 — Kwai's (Kuaishou) groundbreaking unified multimodal video model that fuses text, images, and clips into seamless generations via a single input box. Powered by MVL architecture and Chain-of-Thought reasoning, it nails physics, consistency, and creativity, outperforming Veo 3.1 and Runway Alpha on benchmarks like 247% win rate in image-reference tasks. Now live on LiblibAI with a chat-style UI, early creators are churning 10s cinematic shorts in seconds, signaling the death of tool-hopping workflows.

Runway Unveils Gen-4.5 "David": The Underdog AI Video Model Crushing Google Veo 3 and OpenAI Sora 2 with Cinematic Realism
Runway launched Gen-4.5 on December 1, 2025 — its frontier video generation model codenamed "David" (a biblical nod to slaying giants), topping the Video Arena leaderboard with 1,247 Elo points for unmatched motion quality, prompt adherence, and visual fidelity. Built on NVIDIA Hopper/Blackwell GPUs, it crafts high-definition, physics-accurate clips from text prompts, handling complex scenes with object permanence and causal reasoning that outpace rivals. Rolling out now to all users, early creators report 5x faster Hollywood-grade shorts, fueling Runway's $3.55B valuation surge.

NVIDIA Unleashes Alpamayo-R1: The Reasoning VLA That Gives Autonomous Driving a Brain — Open-Sourced for Level 4 Domination
NVIDIA dropped Alpamayo-R1 on December 3, 2025 — the world's first industry-scale open-source reasoning Vision-Language-Action (VLA) model for AVs, fusing chain-of-thought reasoning with trajectory planning to conquer long-tail edge cases like erratic pedestrians or foggy merges. Trained on a massive 1,727-hour multi-country dataset, it outputs explainable "thoughts" in plain English before steering, slashing decision latency by 40% in sims. Now live on GitHub and Hugging Face with the AlpaSim eval framework, it's a direct shot at Tesla's black-box FSD and Waymo's data moats — early benchmarks show 25% better safety scores in rare scenarios.
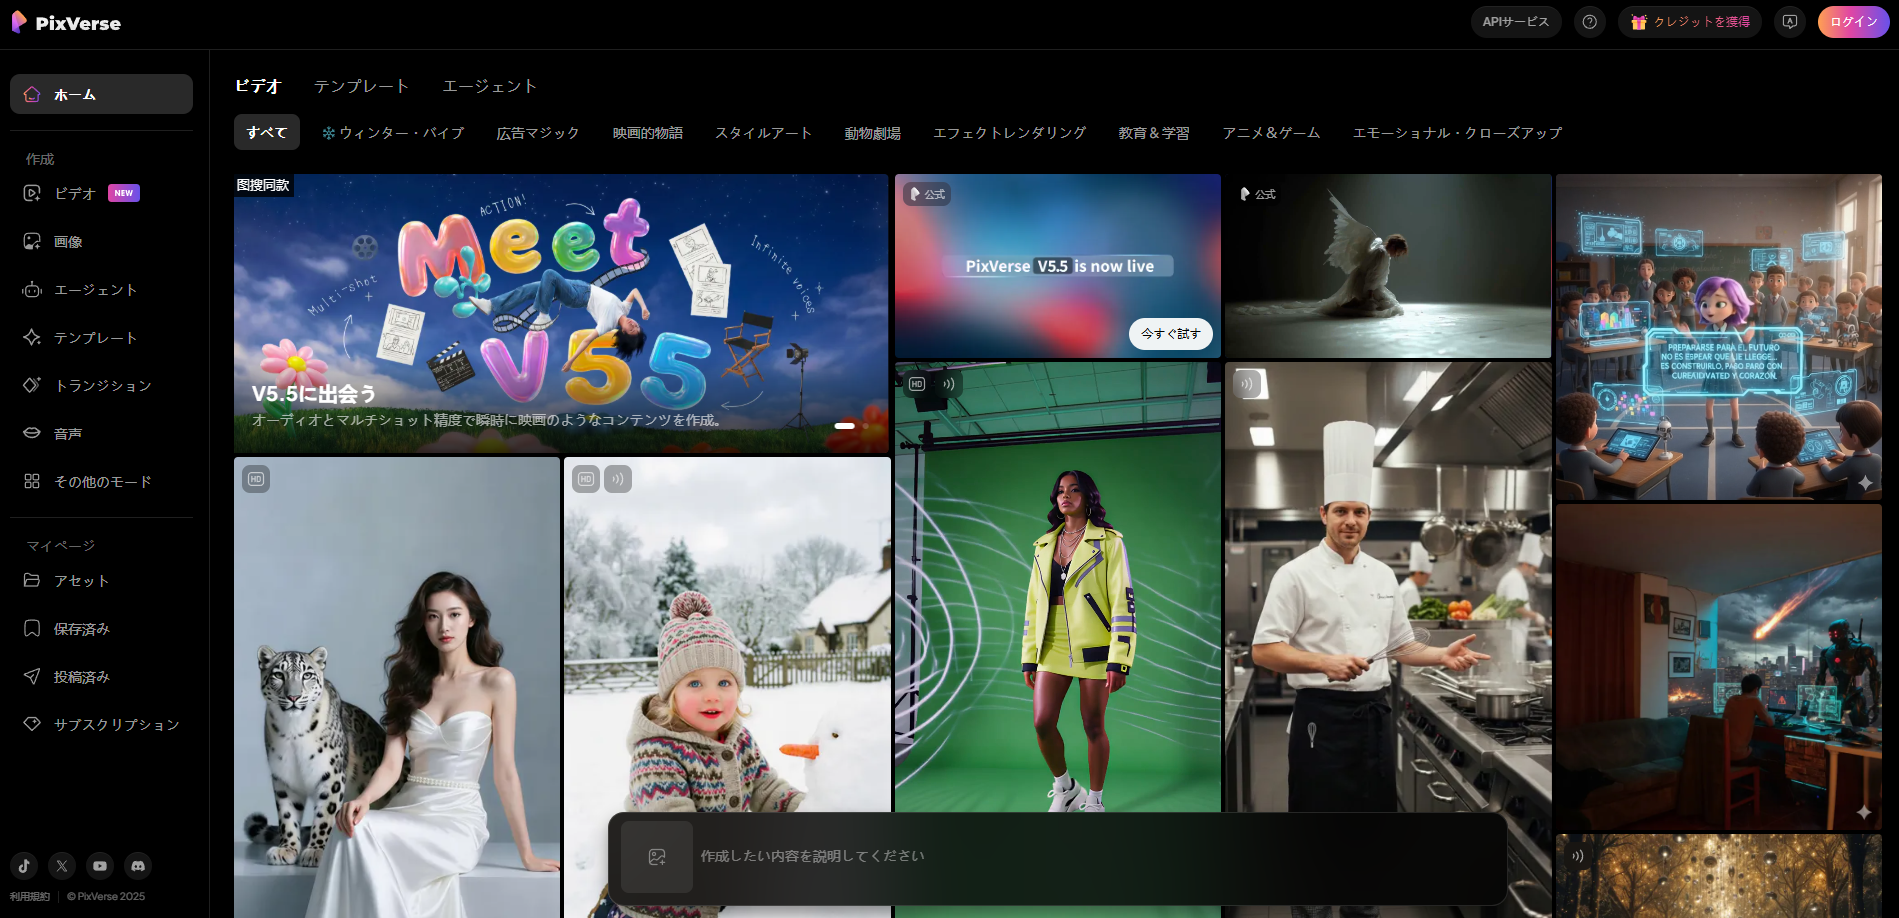
PixVerse V5.5 Drops: Director-Level Audio-Visual Sync in One Click — Turning Prompts into Cinematic Short Films Overnight
AiShi Technology unleashed PixVerse V5.5 on December 4, 2025 — China's first AI video powerhouse with multi-camera narrative generation and seamless audio-visual synchronization. From a single text prompt or image, it auto-scripts multi-shot sequences with lip-synced dialogue, ambient SFX, and BGM, outputting polished 1080p clips in 5-10 seconds. No more stitching clips or manual syncing: this "director-mode" beast has already hooked 100M+ users, with ARR blasting past $40M. Early tests show it outpacing Runway Gen-3 and Kling in narrative flow, making pro-level shorts accessible to anyone with a keyboard.