Mistral Large 4 Review 2026: 1.05T MoE and a 50% Pricing Gap
Category: Tech Deep Dives
This analysis was written by the aifreetool Editorial Team — a group of full-time AI-industry researchers and writers who verify every claim against primary sources. Last updated October 20, 2026. We keep no affiliate relationship with the companies covered here.
TL;DR: Mistral Large 4 — internally nicknamed "Le Chonk" — is a 1.05-trillion-parameter mixture-of-experts model with only 49 billion parameters active per token, live in API preview since October 6, 2026. It leads open-weight rivals on cybersecurity and coding-agent benchmarks, but Mistral's own price sheet and its live product page disagree by exactly 50%, and the promised open-weight release around October 27 still has no published license. Here's what the architecture, the benchmarks, and the pricing gap tell you about whether to adopt it now.
Mistral Large 4 is the first European trillion-parameter open-weight contender, and the company is not being shy about the framing: trained from scratch in about two months on 3,800 NVIDIA Grace Blackwell GPUs in Mistral's own European datacenters, covering more than 160 languages including every official EU language. That sovereignty pitch is coherent. But the more interesting story for developers is the gap between what Mistral advertises and what independent evaluators measure.
The Architecture: MoE Done at Trillion Scale
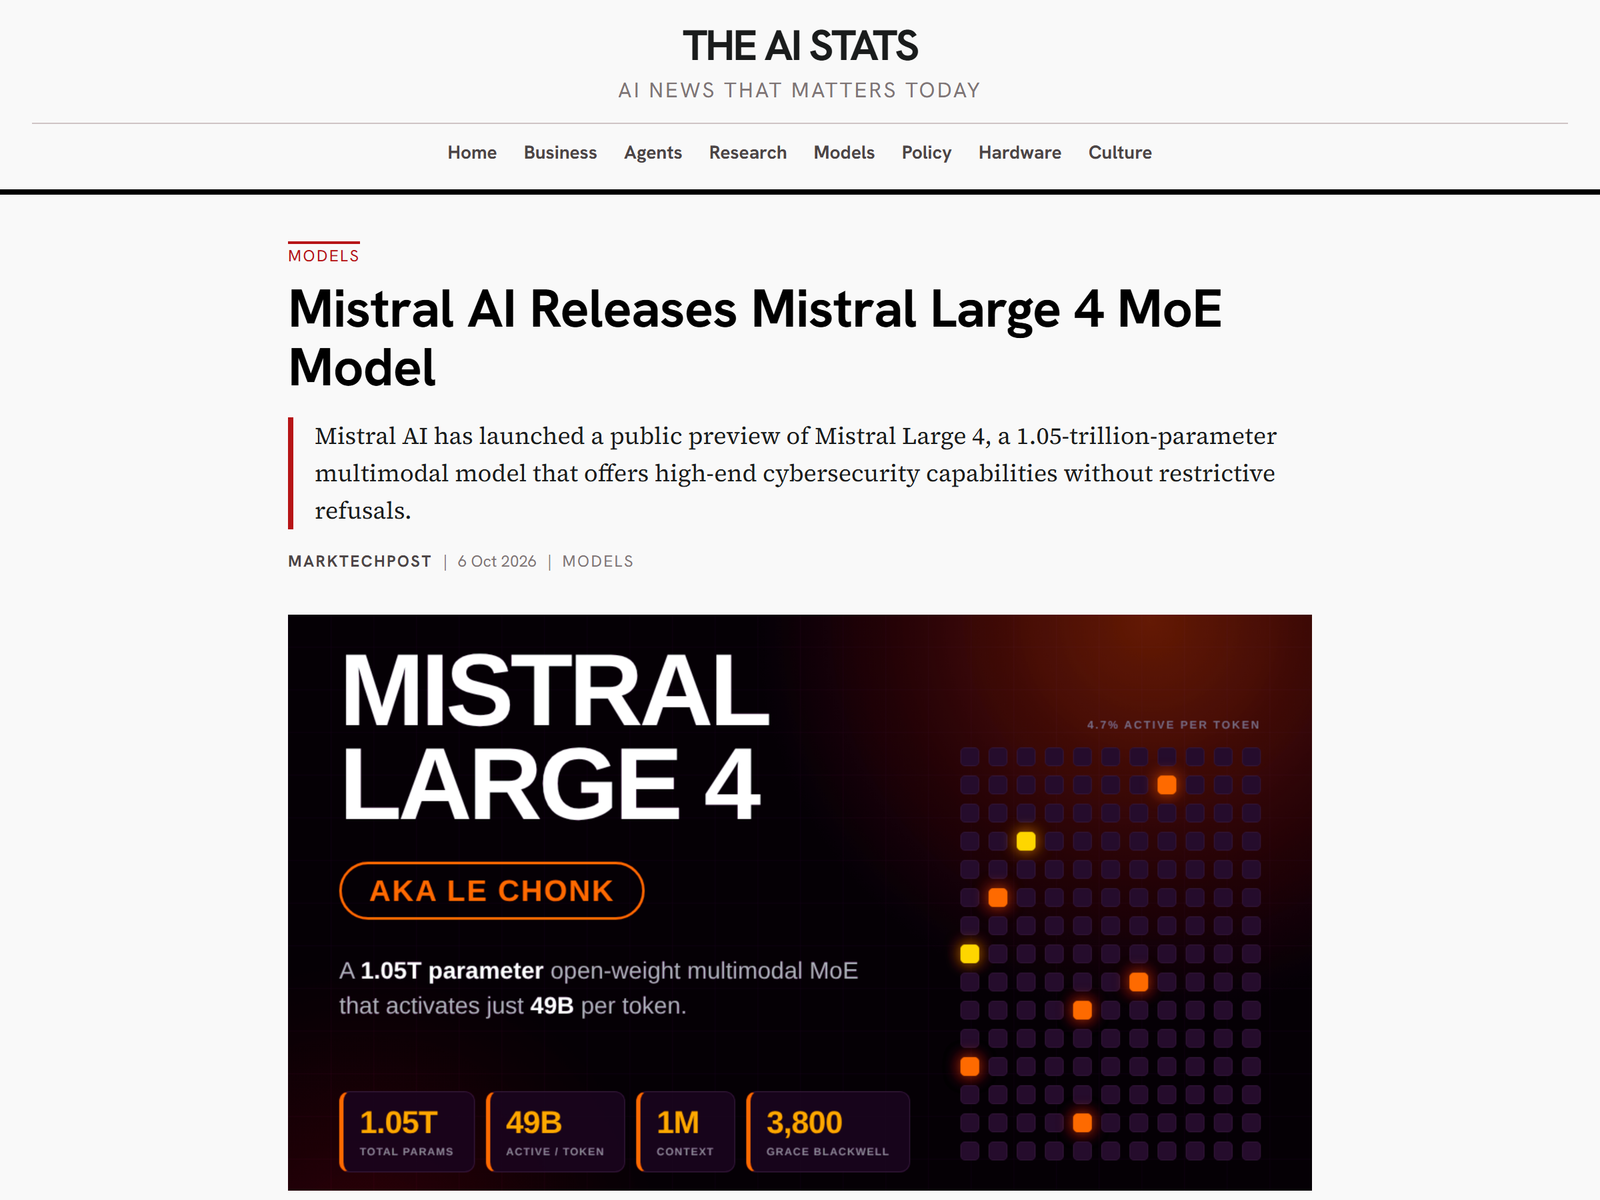
Le Chonk is a sparse mixture-of-experts model: 1.05 trillion total parameters with 49 billion active per request — about 4.7% of the weights fire on any given token. That is the entire point of the design. You get the knowledge capacity of a trillion-parameter model while paying inference costs closer to a 49B dense model, which is why Mistral can serve it at mid-tier pricing. The model is natively multimodal on input (text plus images, via a 1.6-billion-parameter vision encoder) but outputs text only, and it fuses instruct, reasoning, and agentic behavior in one checkpoint.
One discrepancy matters for planning: Mistral's model card claims a 1 million-token context window, but independent evaluators report usable limits in the 512K–524K range. If your agent architecture assumes a full million tokens of working memory, test the real ceiling before committing — long-context agent loops are precisely where this model's cheap cached input pricing ($0.07 per million tokens on the discounted rate) is supposed to shine.
Benchmarks: Where Le Chonk Genuinely Leads
Cybersecurity is the headline. Mistral reports 93% on Cybench and 82% on CyberGym-E2E, a reproduce-and-patch vulnerability test where Mistral says other frontier closed models score near zero — because they refuse defensive-security tasks. On agentic coding, the model posted 61.7% on DeepSWE v1.1, 59.4% on SWE-Atlas-QnA, and 28.3% on Terminal-Bench 4.0, for a 49.8% Coding Agent Index that Mistral says puts it ahead of DeepSeek V4 Pro (57% on DeepSWE) and Qwen 3.8 Max.
The independent picture is more mixed. Artificial Analysis scored it 38 on its Intelligence Index — comparable to GPT-6 Luna (max) at 38 — ranking 64th of 225 models tracked, and calculated that it costs more than four times as much per completed task as similarly capable open-weight competitors. In Surge AI's blind human evaluation, annotators rated Le Chonk 3.74 out of 5, ahead of GLM-5.3 (3.60) and Kimi K3 (3.59) but behind Claude Opus 5 at 4.22. Specialist strengths are real: 15.83% on the Harvey Legal Agent Benchmark leads several larger models, and it edges GPT-6 Astra by one point (42% vs 41%) on the Dense200 vision-localization test.
The Pricing Gap Nobody Has Reconciled
| Metric | Mistral price sheet | Live product page |
|---|---|---|
| Input / million tokens | $1.36 | $0.68 |
| Cached input / million | $0.14 | $0.07 |
| Output / million tokens | $4.18 | $2.09 |
That is an exact 50% gap, which trackers describe as an unlabeled launch discount — the crossed-out rates on the model card imply a preview discount, but Mistral has offered no explanation of which price survives the preview period. For comparison, Kimi K3 charges $3.00 input / $15.00 output per million tokens, and GLM-5.3 charges $1.40 / $4.40. If you budget against the discounted rate and the discount expires, your inference bill doubles overnight. At Mistral's September funding — €3 billion led by ASML at a €21 billion valuation — the company can afford preview pricing, but enterprise buyers shouldn't build cost models on a coin flip.
- Key Takeaways:
- Mistral Large 4: 1.05T parameters, 49B active per token (4.7% activation), natively multimodal input.
- Leads on Cybench (93%) and CyberGym-E2E (82%); independent Intelligence Index is 38, ranked 64/225.
- Price sheet says $1.36/$4.18; live page bills $0.68/$2.09 — an unexplained 50% preview discount.
- Open weights due around October 27, 2026, but no license terms published yet.
- Claimed 1M-token context is reported by evaluators as 512K–524K in practice.
My Take / The Bottom Line
My take: Le Chonk is a legitimate flagship and the European-sovereignty story is real, but this is a model to pilot, not a model to migrate onto. The verdict splits cleanly. Best for: European enterprises with data-residency requirements who need defensive-security or legal-document workloads, and teams that can exploit the $0.07/M cached-input rate for long agent loops. Trade-off: on generalist workloads it ranks mid-pack independently and costs 4x more per completed task than equally capable open-weight rivals, so run your own eval before committing. The decisive moment is the open-weight release around October 27: if the license lands permissive and the pricing question is answered, this becomes the default self-hosted frontier option for EU-regulated buyers. If the license turns restrictive, the sovereignty pitch loses most of its teeth. Wait one more week before signing anything long-term.
FAQ
Q: What is Mistral Large 4's parameter count?
A: 1.05 trillion total parameters in a sparse mixture-of-experts architecture, with about 49 billion active per token, plus a 1.6-billion-parameter vision encoder.
Q: When do the Mistral Large 4 open weights release?
A: Mistral has promised weights around October 27, 2026, but has not yet published the license terms.
Q: How much does Mistral Large 4 cost?
A: The live product page bills $0.68 per million input and $2.09 per million output tokens; Mistral's own price sheet lists $1.36/$4.18, an unexplained 50% preview discount.
Q: Is Mistral Large 4 good for coding?
A: It scored 61.7% on DeepSWE v1.1 and 49.8% on Mistral's Coding Agent Index, ahead of DeepSeek V4 Pro, but behind Claude Opus 5 in blind human evaluation (3.74 vs 4.22 out of 5).
Explore it on our site: browse our AI model hub or see our Mistral Large 4 listing or Mistral's coding-focused Codestral.