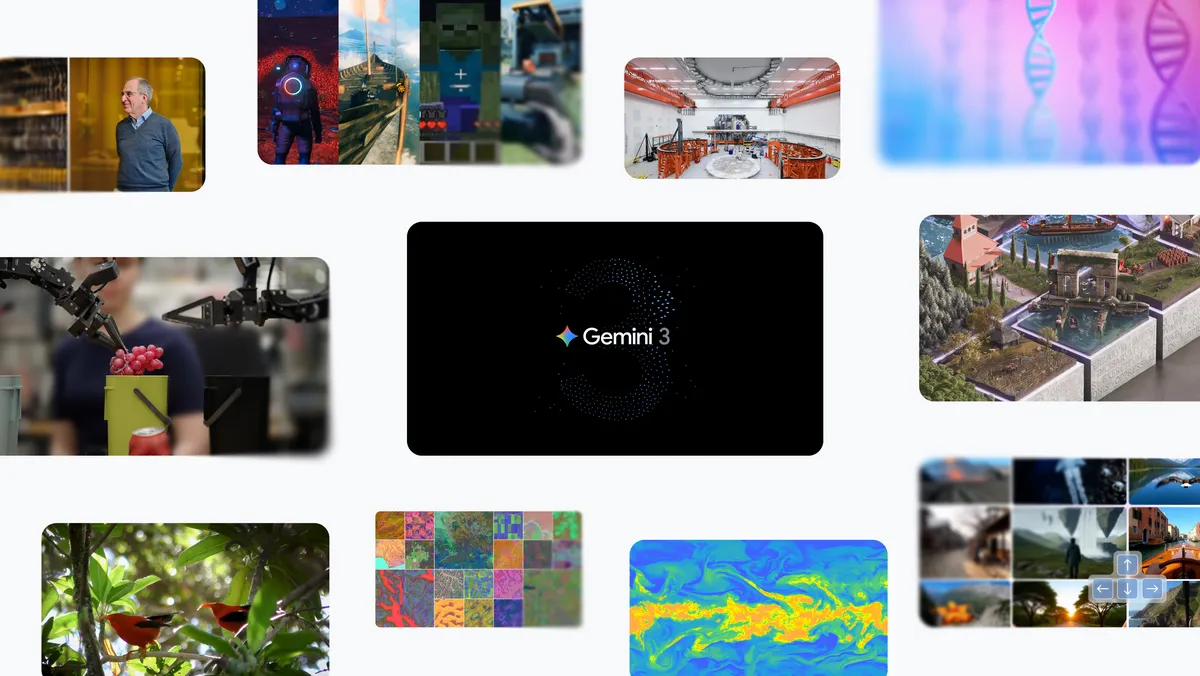
Google Drops 2025 Research Recap: 8 Massive Breakthroughs from Long-Context Mastery to Multimodal Reasoning, Solidifying Its AI Foundations
On December 23, 2025, Google published its annual research review, spotlighting eight pivotal breakthrough areas that defined the year for Google Research and DeepMind. From revolutionary long-context processing and native multimodal understanding to agentic systems, model efficiency, generative media, scientific discovery, quantum leaps, and responsible AI frameworks, these advances — powered by milestones like Gemini 3 and Gemma 3 — transformed AI from experimental tool to everyday utility, with real-world deployments accelerating innovation across science, productivity, and global challenges.
Microsoft × PKU × SJTU Unveil QFANG: The Breakthrough Scientific LLM That Bridges Computational Design to Lab Execution in Materials Synthesis
On December 16, 2025, a collaborative team from Microsoft Research Asia, Peking University, and Shanghai Jiao Tong University released QFANG — a groundbreaking large language model specialized for organic and inorganic materials synthesis procedure generation. Trained on over 900,000 reaction-procedure pairs with chemistry-guided reasoning and reinforcement learning from verifiable rewards, QFANG achieves +22% accuracy in synthesis prediction and slashes R&D cycles by 40% in early lab tests. This closes the infamous "compute-to-lab" gap, turning in-silico designs into executable experiments with unprecedented reliability.

MiniMax Hailuo Video Team Drops VTP: The First Open-Source Scalable Visual Tokenizer Pre-Training Framework — Revolutionizing Generative Video Pipelines
On December 16, 2025, the MiniMax Hailuo Video team officially open-sourced VTP (Visual Tokenizer Pre-training) — a groundbreaking unified framework for pre-training visual tokenizers optimized for downstream generation tasks. By jointly optimizing contrastive, self-supervised, and reconstruction losses, VTP creates semantic-rich latent spaces that scale dramatically better than traditional autoencoders, delivering 65.8% FID gains in DiT-based video/image generation with just more pre-training FLOPs. Models (0.2B-0.3B) and code are now live on GitHub and Hugging Face, empowering the community to build next-gen Hailuo-level video models without starting from scratch.

Moore Threads' LiteGS Takes Silver at SIGGRAPH Asia 2025: China's Homegrown 3DGS Tech Accelerates Training 10x While Open-Sourcing the Future of Reconstruction
On December 17, 2025, Moore Threads stunned the graphics world by clinching silver in the 3D Gaussian Splatting Reconstruction Challenge at SIGGRAPH Asia 2025 in Hong Kong. Their self-developed LiteGS framework — a full-stack co-optimized powerhouse — delivers up to 10.8x faster training with half the parameters compared to baselines, while lightweight variants hit equivalent quality using just 10% training time and 20% params. Fully open-sourced on GitHub today, LiteGS is igniting global collaboration in real-time 3D reconstruction for AR/VR, robotics, and beyond.
Finland's VTT Unveils MISEL Breakthrough: Bio-Inspired Edge Vision System Lets Robots Operate Offline in Disaster Zones — No Network, No Heavy Batteries Needed
VTT Technical Research Centre of Finland announced the completion of the EU-funded MISEL project on December 11, 2025 — delivering a neuromorphic machine vision system that mimics human retina-brain cooperation via embedded low-power circuits. This edge-computing marvel enables drones and robots to perceive, interpret, and act autonomously in harsh environments like post-earthquake rubble, slashing energy use while ditching cloud dependency. Early prototypes promise fruit-fly-level efficiency, with applications spanning rescue ops to industrial monitoring — a game-changer for embodied AI in real-world chaos.
University of Waterloo Unveils SubTrack++: The Breakthrough Training Method That Slashes LLM Pre-Training Time by 50% While Boosting Accuracy
Researchers at the University of Waterloo launched SubTrack++ on December 9, 2025 — a revolutionary gradient subspace tracking technique that cuts large language model pre-training time by up to 50% (with arXiv benchmarks showing even 65% gains), maintains identical memory footprints, and surpasses state-of-the-art accuracy. Developed in the Critical Machine Learning Lab, this open-approach democratizes LLM building by slashing costs and energy use, with the paper set for spotlight at NeurIPS 2025. Early evals on 1B-parameter models confirm SOTA convergence, paving the way for greener, more accessible frontier AI.

Mistral AI Unleashes Mistral 3: The Apache 2.0 Open-Source Powerhouse Family Crushing Proprietary Giants with Edge-to-Frontier Multimodal Might
Mistral AI launched the Mistral 3 series on December 2, 2025 — a blockbuster family of 10 fully open-weight multimodal models under the permissive Apache 2.0 license, spanning Ministral 3 (3B/8B/14B dense variants in base, instruct, and reasoning flavors) to the beastly Mistral Large 3 (675B total params MoE with 41B active). Optimized for everything from drones to datacenters, these models nail image understanding, non-English prowess, and SOTA efficiency, debuting at #2 on LMSYS Arena OSS non-reasoning while slashing token output by 10x in real-world chats. This full-line return to unrestricted commercial openness is a direct gut punch to closed ecosystems like OpenAI and Google.

SenseTime Unleashes NEO Architecture: The Native Multimodal Revolution That Fuses Vision and Language at the Core — Open-Sourced to Shatter Efficiency Barriers
SenseTime, in collaboration with Nanyang Technological University's S-Lab, launched the NEO architecture on December 5, 2025 — the world's first scalable, open-source native Vision-Language Model (VLM) framework that ditches modular "Frankenstein" designs for true bottom-up fusion. Featuring pixel-direct embedding, Native-RoPE for spatiotemporal harmony, and hybrid attention mechanisms, NEO achieves SOTA performance on benchmarks like MMMU and MMBench with 90% less training data than GPT-4V. The 2B and 9B models are now live on GitHub, with video/3D extensions slated for Q1 2026, igniting a paradigm shift toward edge-deployable multimodal brains.

ByteDance Unveils Depth Anything 3: The Transformer That Reconstructs 3D Worlds from Any Views — SOTA Geometry Without the Hassle
ByteDance's Seed Team launched Depth Anything 3 (DA3) on November 14, 2025 — a groundbreaking visual spatial reconstruction model that fuses arbitrary images into consistent 3D geometry using a single plain transformer and depth-ray prediction. Open-sourced on GitHub with three model series (Giant for any-view, Metric for scale-aware, Nested for metric fusion), it crushes VGGT by 35.7% in pose accuracy and 23.6% in reconstruction, while matching Depth Anything 2's monocular detail. From robotics to VR, DA3's one-pass inference slashes complexity, powering Blender addons and Hugging Face demos — a minimalism masterstroke in 3D perception.

Anthropic Unleashes Claude Opus 4.5: The Coding Colossus That Reclaims SOTA Crown, Powers Agents, and Crushes Costs by 66%
Anthropic launched Claude Opus 4.5 on November 24, 2025 — its frontier flagship that's now the undisputed king of coding, agentic workflows, and computer use. Blending enhanced memory for endless chats, a tunable "effort" slider for 21% smarter reasoning at 66% lower costs, and integrations like Claude for Chrome/Excel, it smashes benchmarks: 80.9% on SWE-Bench Verified (first over 80%), 15% leap on Terminal Bench, and SOTA on GPQA Diamond and ARC-AGI 2. Available now via API and apps for Pro/Max/Team users, this beast outpaces GPT-5.1 and Gemini 3 Pro while slashing token bills — a paradigm-shifting efficiency bomb in the AI arms race.
Tencent's HunyuanOCR Goes Open Source: 1B-Parameter Beast Crushing SOTA in Document Parsing, Multilingual Translation, and Beyond
Tencent Hunyuan unveiled HunyuanOCR on November 25, 2025 — a groundbreaking 1B-parameter end-to-end OCR model that's now fully open-sourced on GitHub. Built on Hunyuan's native multimodal architecture, it dominates benchmarks like OmniDocBench (94.1 score, topping Google Gemini 3-Pro) and OCRBench (860 total, SOTA for <3B models), excelling in complex docs, 9-scenario text detection (handwriting, ads, videos), and 14-language translation (ICDAR 2025 small-model champ). Lightweight at 2GB, it deploys on consumer GPUs with zero cascade errors — a game-changer for devs ditching bloated VLMs.

Challenging NVIDIA's Throne: ZAYA1 Debuts as the First Major AI Model Trained Purely on AMD Hardware
On November 24, 2025, Zyphra unveiled ZAYA1 — the world's first large-scale Mixture-of-Experts (MoE) foundation model trained entirely on AMD Instinct MI300X GPUs, Pensando networking, and ROCm software stack, in collaboration with AMD and IBM Cloud. This 8.3B-parameter beast (760M active) crushes benchmarks, outperforming Meta's Llama-3-8B and rivaling Google's Gemma3-12B in reasoning, math, and coding — all while slashing training costs and complexity with 192GB HBM memory. A seismic proof-of-concept that shatters NVIDIA's monopoly, ZAYA1 signals AMD's breakout in frontier AI, with early adopters eyeing hybrid clusters for 10x faster saves and open-source flexibility.
- Previous Page
- 1
- ···
- 4
- 5
- 6
- 7
- Total 7 pages
Why OpenAI Fired Three Safety Researchers in 2026: Trust Dispute
10/16/2026
Why Anthropic Bet $150 Million on Federal Science in 2026
10/16/2026
VPN Proxy Master Review 2026 - Streaming Servers, Real Limits
10/16/2026
Touch VPN Review 2026 - Free, but Read the Privacy Fine Print
10/16/2026
Browsec Review 2026 - A Browser-First VPN, Read the Fine Print
10/16/2026
How to Make Money Building 3D Web Experiences With Spline in 2026
10/14/2026
Claude Dashboards and Motion Review 2026: End of the BI Ticket
10/13/2026
Claude Haiku 5.5 Pricing Review 2026: $0.10 per Million Tokens
10/13/2026
How to Make Money Designing Logos With LogoAI in 2026
10/13/2026