Obsidian Security delivers complete SaaS security—gain control, stop threats, and ensure compliance across all your business apps.

Unified LLM Observability and AI Agent Evaluation Platform for AI Applications—from development to production.

Release high-quality LLM apps quickly without compromising on testing. Never be held back by the complex nature of LLM interactions.
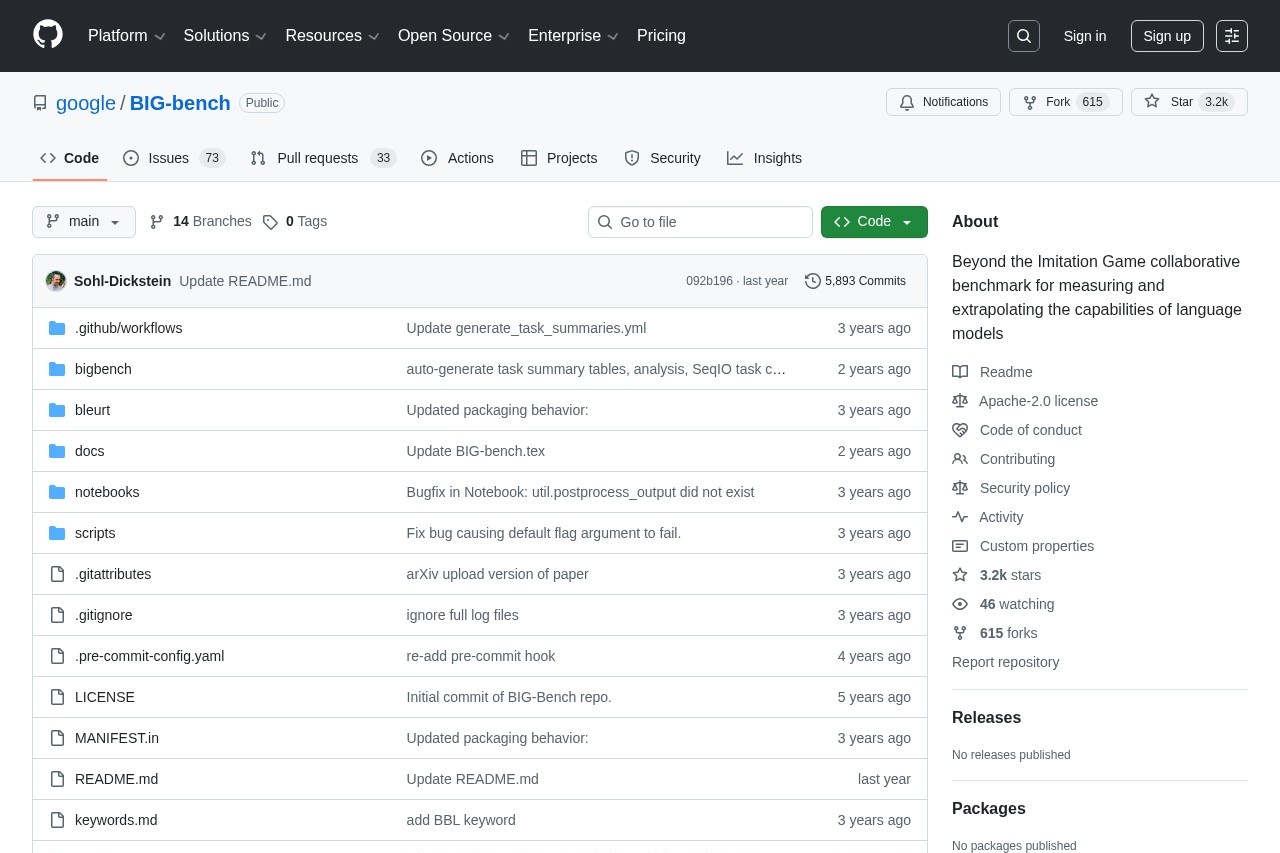
BIG-bench remains a landmark open-source benchmark suite in late 2025, featuring over 200 diverse tasks that probe reasoning, creativity, social understanding, and more. Though many tasks are now solved by frontier models, its breadth makes it ideal for broad capability assessment and historical comparison—completely free, community-driven, and easy to run.

OpenRouter stands as the leading unified AI model API platform in late 2025, providing seamless access to over 605 models from dozens of providers through a single endpoint. Features like intelligent routing, automatic fallbacks, transparent pricing, and valuable usage analytics make it indispensable for developers seeking reliability and cost efficiency.
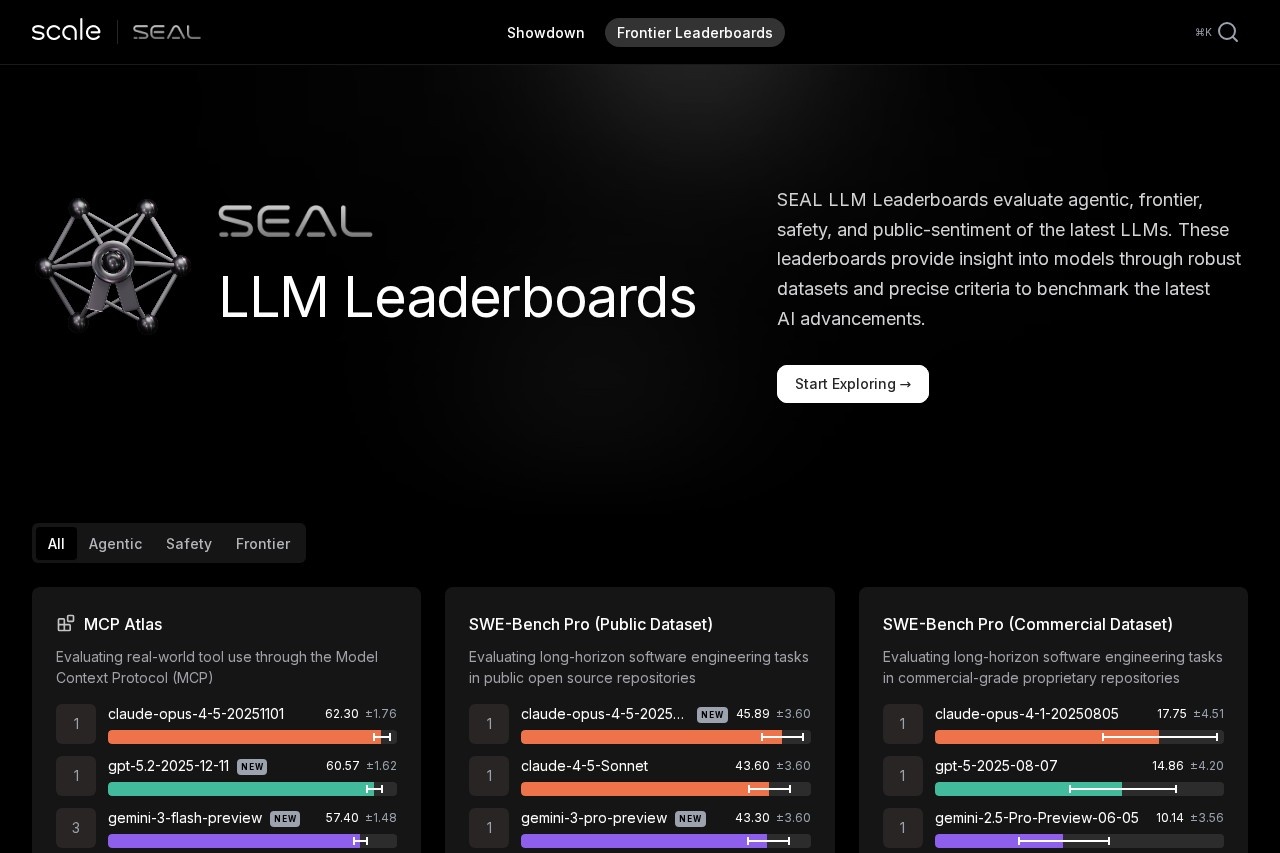
Scale SEAL Leaderboard remains the gold standard for trustworthy LLM rankings in late 2025. Using private datasets to avoid contamination, it rigorously evaluates frontier models across agentic, reasoning, coding, multimodal, and safety benchmarks—Claude Opus 4.5, GPT-5 series, and Gemini 3 Pro consistently lead.

Traceloop excels as the top open-standards LLM observability platform in late 2025, built on OpenLLMetry (OpenTelemetry). It offers instant tracing, automated quality checks, custom evaluators, and deep integrations—ideal for catching issues before production.

Arize Phoenix stands out as the premier open-source LLM observability platform in late 2025. It delivers powerful tracing, interactive embeddings visualization, built-in evaluations, and drift detection—completely free and self-hostable.

Lilac AI excels as an open-source platform for curating unstructured text datasets for LLMs, offering fast clustering, semantic search, PII detection, and concept tagging. Acquired by Databricks in 2024, it integrates seamlessly for enterprise scale—ideal for improving data quality in fine-tuning, RAG, and evaluation workflows.
Giskard AI excels as the top LLM red teaming platform in late 2025, delivering automated vulnerability detection for hallucinations, jailbreaks, biases, and harmful outputs in AI agents. Key strengths include sophisticated attack generation, human-in-the-loop collaborative dashboards, proactive monitoring, and robust enterprise compliance (SOC 2, GDPR, on-premise). Trusted by companies like Michelin and BNP Paribas, it bridges development and security teams effectively. The open-source version offers solid basics for individuals, while Giskard Hub provides advanced automation and team features—ideal for regulated industries deploying production LLM agents.

Comet ML excels in late 2025 as a versatile MLOps platform combining robust experiment tracking with advanced LLM observability through Opik. It delivers real-time visualizations, seamless integrations, prompt optimization, and production monitoring—trusted by innovative teams seeking reproducible workflows.

Vellum AI remains the premier LLMOps platform in late 2025, providing an end-to-end solution for building, evaluating, deploying, and monitoring production LLM applications. Its visual workflow builder, comprehensive evaluations, git-like versioning, and robust observability set the standard for teams shipping reliable AI products.

METR (Model Evaluation & Threat Research) leads AI safety efforts in late 2025 as a nonprofit evaluating frontier models for catastrophic risks. It focuses on autonomous capabilities, R&D acceleration, and evaluation integrity—publishing transparent reports and developing benchmarks like RE-Bench and MALT.

Geekbench AI remains the leading cross-platform AI benchmark in late 2025, measuring real-world machine learning performance across CPU, GPU, and NPU with precision-specific scores.

MLCommons aims to accelerate AI innovation to benefit everyone. It's philosophy of open collaboration and collaborative engineering seeks to improve AI systems by continually measuring and improving the accuracy, safety, speed and efficiency of AI technologies. We help companies and universities around the world build better AI systems that will benefit society.

Open LLM Leaderboard remains the premier community-driven benchmark for open-source large language models in late 2025. It provides transparent rankings across challenging tasks, helping developers and researchers identify top-performing open models reliably.

Artificial Analysis remains the leading independent AI benchmarking platform in late 2025. It delivers rigorous comparisons of LLMs and multimodal models across intelligence, speed, price, hallucination, and openness—trusted for transparent, vendor-neutral evaluations.
OpenAI Evals remains the leading open-source LLM evaluation framework in late 2025. It features a comprehensive registry of benchmarks, easy YAML templates for custom creation, model-graded scoring, and secure private testing—perfect for reproducible LLM evaluation without data exposure.
Guardrails AI remains the premier open-source platform for LLM safety in late 2025, offering the largest community-driven Guardrails Hub with validators for toxicity, PII leaks, hallucinations, prompt injections, and more. It ensures reliable outputs with minimal latency, integrates seamlessly as a drop-in LLM wrapper, and includes tools like Snowglobe for pre-launch testing. Free for developers; enterprise managed service adds production deployment and observability. Trusted for building safe, compliant GenAI applications.
DeepChecks excels as a specialized LLM evaluation platform in late 2025, providing robust auto-scoring, customizable judges, version comparison, and seamless CI/CD/production monitoring. It handles complex agentic workflows and reduces hallucinations effectively—perfect for AI teams releasing high-quality generative apps.
- Previous Page
- 1
- 2
- 3
- Total 3 pages

How to Build a $3,000+/Month AI Animated Digital Products Agency on Etsy in 2026 Using PixVerse v5.5 + Claude
01/12/2026
Botpress + WordPress: Launch a Productized AI Chatbot Agency (Setup Fee + Monthly Retainer)
01/23/2026
Arm Establishes Dedicated Physical AI Division: A Strategic Pivot to Own the AI Hardware Stack from Silicon to Embodied Intelligence
01/10/2026
LiquidVPN Review 2026 – Cheap VPN with IP Modulation
09/07/2026
Anthropic Secures $2 Billion Mega-Round: Amazon Leads $20B+ Valuation Push as Claude 4 Era Accelerates
01/11/2026